When the leader stops shipping
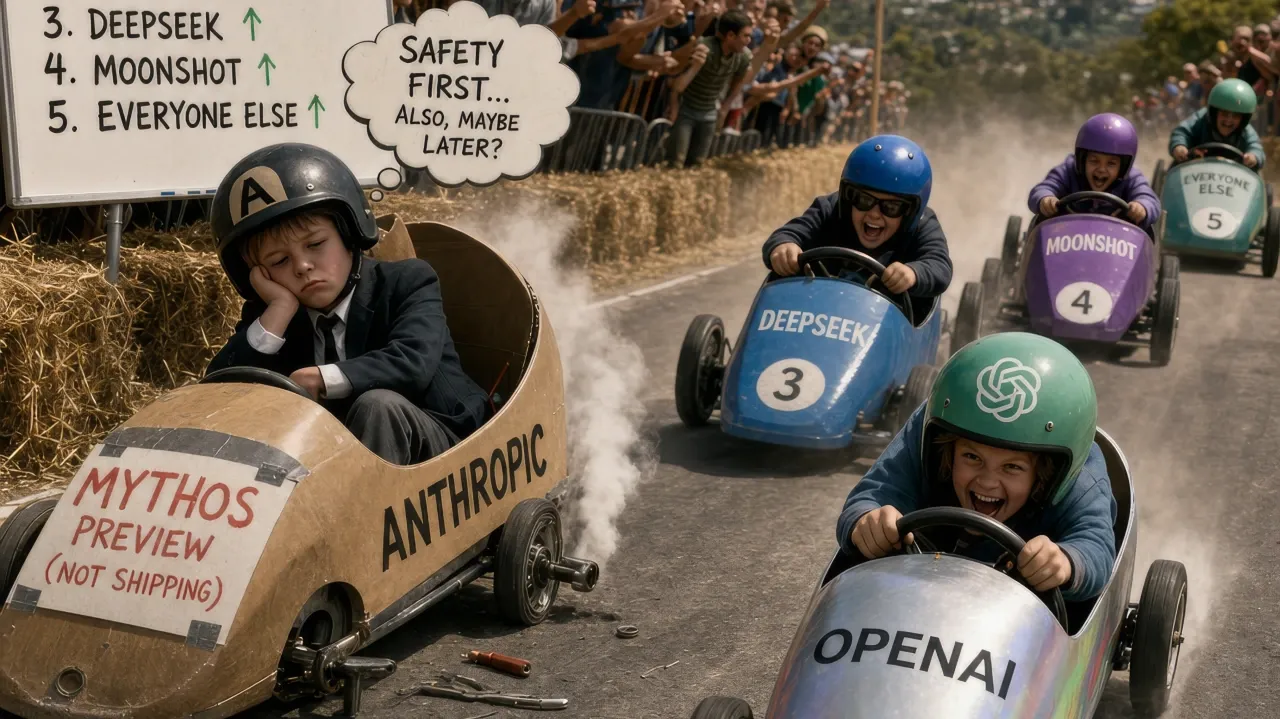
Generation outpaced review. Now the review is catching up and the company that should be leading has stopped shipping.
I wrote a piece a while back arguing that AI-assisted development is generating an accelerating technical debt crisis, and that organisations need something I called a Slop Protection Team to handle the volume of code being produced relative to the volume that can be properly reviewed. The thesis was that generation has outpaced review and that the gap is widening fast enough to be a structural problem.
Since then, two things have happened. The models are getting genuinely better at the easier half of review, and the strategic environment around those models has become considerably more chaotic than I anticipated. Both are worth writing about, and they connect.
Review is starting to catch up, on the parts that are easy to reward
The mechanism behind the improvement is not surprising once you look at what the labs have published. Meta’s SWE-RL paper described training on GitHub pull request data with rewards calculated from how well the generated patch matched the oracle patch, using group relative policy optimisation. That approach generalised, with reported gains on out-of-domain tasks where supervised fine-tuning baselines actually degraded performance. Frontier labs have not described their training recipes in that level of detail, but the public results suggest a similar direction. Train on real engineering activity, reward verifiable correctness, watch the capability curve bend.
The benchmark numbers reflect this. SWE-bench Verified leadership has moved from the high seventies at the start of the year to GPT-5.5 at 88.7% and Claude Opus 4.7 at 87.6%, both leaning on the same underlying approach. On SWE-bench Pro, the harder cousin, Opus 4.7 holds the lead at 64.3% with GPT-5.5 at 58.6%. The point is not the rivalry between specific models. The point is that on a benchmark designed two years ago to be difficult, both leading models are now closing in on saturation.
In practice this shows up as code review tools that actually work. Martian’s Code Review Bench measured CodeRabbit at a 2.3% false positive rate across roughly 300,000 pull requests over two months in January and February of this year, which is a meaningful number against an industry average historically sitting somewhere between 5% and15%. Independent parallel-runner studies broadly support the result, with the trade-off being latency rather than accuracy. The tool now takes about ten minutes to come back with a thorough review. A few months ago that would have been a complete review cycle for a junior reviewer. Now it is the time-to-first-comment for software.
METR’s update from February of this year is the other useful signal. Their original study, which became famous for finding that AI made experienced developers 19% slower, could not be reliably replicated when they tried to run it again. The reason is itself interesting. Too many developers refused to participate in the control group because they would no longer agree to work without AI assistance. Selection effects ate the methodology. METR’s own honest conclusion was that AI likely does provide productivity benefits in early 2026, but their study design can no longer measure it. Make of that what you will, but a methodology breaking because the control condition has become commercially unviable is a strong signal about where the ground has moved.
Architecture and security are still genuinely behind
The harder half of the review has not closed in the same way. ProgramBench, published this month, evaluated end-to-end software generation by asking models to reconstruct complete projects from documentation and behavioural specifications. The headline finding was that no evaluated model fully reconstructs complete software projects, with top models achieving 95% test pass on only 3% of tasks. The more interesting finding was structural: language-model-generated codebases are notably monolithic and structurally distinct from human-authored implementations.
Set that next to John Ousterhout’s central thesis in A Philosophy of Software Design, which is that managing complexity is the core challenge of software design, and that complexity manifests through change amplification, cognitive load, and unknown unknowns. The benchmark numbers suggest models are getting good at managing local complexity, the kind that reinforcement learning on pull request patches teaches directly, and remain weak at the systemic complexity that the book is actually about. There are now a number of published agent skills explicitly based on Ousterhout’s principles, which is a tell. The principles are being externalised as runtime scaffolding rather than internalised in the weights, because patch-matching teaches local correctness and does not naturally teach modularity, information hiding, or interface depth.
Security tells a similar story. The benchmarking literature consistently finds that frontier models over-flag aggressively, raising alarms on functions that are not actually vulnerable while missing the specific statement-level issues that matter. The result is a reviewer that is enthusiastic but imprecise, which is closer to a junior security engineer than a senior one. Useful, but not a replacement.
And then there is Mythos
Which brings us to the strategic question, and the part that prompted me to write this.
On April 7th, Anthropic announced Claude Mythos Preview. Benchmark leads across SWE-bench Verified at 93.9%, Terminal-Bench 2.0 at 82%, OSWorld at 79.6%, CyberGym at 83.1%. The model would not be made generally available, the company said, on safety grounds. The cyber capability in particular was framed as too dangerous to release without controls. A coalition of around fifty critical infrastructure organisations would get access through Project Glasswing, with a hundred million dollars in usage credits.
On April 16th, Anthropic released Opus 4.7 to general availability. Genuinely strong, but not a Mythos-class model.
On April 23rd, OpenAI released GPT-5.5. Terminal-Bench 2.0 at 82.7%, which is slightly ahead of Mythos. OSWorld at 78.7%. CyberGym at 81.8%, which is 1.3 points behind Mythos on the same benchmark Anthropic had described two weeks earlier as too dangerous to release broadly, and that’s against a Mythos score achieved through a multi-agent scaffold rather than the base model alone. VentureBeat counted GPT-5.5 holding state of the art on fourteen benchmarks, and against Opus 4.7 on four and Gemini 3.1 Pro on two, among the models the public can actually use.
On April 20th, Moonshot shipped Kimi K2.6 with open weights at SWE-bench Pro parity with GPT-5.5 and roughly a fifth of the token cost. On April 24th, DeepSeek released V4, competitive on the headline coding benchmarks at fourteen cents per million input tokens.
The lead Anthropic announced eroded in about two weeks across most of the categories that matter for engineering work. Mythos still holds on paper, but it holds while sitting on a shelf, accessible to fifty companies and nobody else. The model Anthropic can actually sell, Opus 4.7, is being out-shipped on agentic benchmarks by GPT-5.5 and out-priced for cost-sensitive workloads by the open weight cohort.
This is not a critique of safety controls. Anthropic is allowed to decide that a particular capability needs gating, and reasonable people can argue about where to draw that line. The critique is about release strategy in a market that has changed faster than Anthropic seems to have noticed. Confident leaders, ship. The Mythos announcement reads like a company explaining why it is not shipping the next thing, while everyone else simply ships. The credibility cost of that posture compounds because the gap between announcement and broad release becomes the window in which everyone else closes the distance.
There is a version of this story where Anthropic shipped Mythos on April 7th as Opus 5.0, with whatever safety controls they thought reasonable, and owned the conversation for a quarter. The version that actually happened is one where they announced the capability, withheld the product, and watched competitors close the technical gap and capture the workloads. Two months on, the leader has slipped from leading. They still make excellent models. They are no longer obviously ahead, and the strategic posture has started to look more like protectionism than confidence.
What this means if you ship code for a living
The optimistic and the cautious points sit alongside each other comfortably. Review of small, well-scoped, verifiable units of work is getting genuinely good, and the tooling is now worth the investment. Review of architecture, security beyond pattern-matching, and design philosophy remains stubbornly hard and is going to remain a human responsibility informed by tooling rather than replaced by it.
The Slop Protection Team thesis does not go away. The work shifts. The tedious half of review, the part that wears senior engineers down without using their judgement, is becoming automatable in a way that was not really true just a couple of months ago. The part that needs human judgement, the architectural and systemic complexity that Ousterhout was writing about, remains exactly where it was. That is roughly the right division of labour. Build for it.
One other thing worth saying. The cohort of models doing this work is turning over every six to eight weeks. The leader on a given Tuesday will be in third place by the end of the month. Anyone building review pipelines tightly coupled to specific model versions is committing to maintenance costs they have probably not budgeted for. The platform investment that pays back is in evaluation infrastructure, tool-agnostic interfaces, and the human capability to do the architectural review that the models are still failing at. The capability gap is closing on one side and the strategic ground keeps moving on the other. Both directions need attention.
Originally published on linkedin.com.